Cloud Computing

Transforming fleet analytics for Novus Hi-Tech through agentic AI

Fleet analytics sounds straightforward until you have thousands of vehicles streaming dashcam footage, driver alerts, GPS pings, and speed warnings across 10 countries, all at the same time. At that scale, no team can manually triage every drowsiness alert or investigate every over-speeding event before it becomes a real incident. With over 120 enterprise customers […]

Transforming fleet analytics for Novus Hi-Tech through agentic AI Read More »

How DeepL keeps closest-exit routing during maintenance with AWS Cloud WAN

DeepL is a Language AI company that builds written and real-time AI voice translation products used by more than 200,000 business teams worldwide. Its infrastructure spans multiple AWS Regions across Europe, North America and Asia, with hybrid connectivity back to two European data centers. Taking a single AWS Direct Connect link out of service for

How DeepL keeps closest-exit routing during maintenance with AWS Cloud WAN Read More »

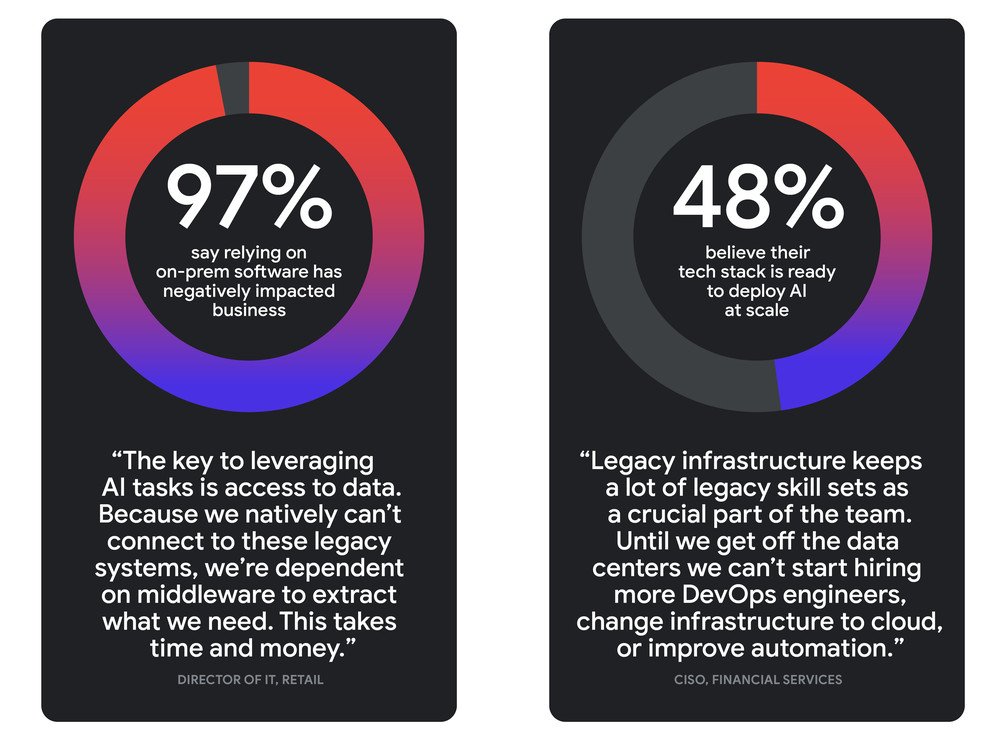
New survey finds enterprises trapped between legacy software and AI modernization

Throughout my career in cybersecurity and infrastructure protection — both in government and now at Google Cloud — I have consistently seen that friction between new and existing technology is often a barrier to progress. A new piece of software or service may work wonderfully on its own but then it’s placed within a complex,

New survey finds enterprises trapped between legacy software and AI modernization Read More »

Now generally available: GKE dynamic slicing for higher resilience, and efficiency for TPUs

Running large-scale AI workloads on TPU and Google Kubernetes Engine (GKE) requires infrastructure that adapts as fast as your models change. Dynamic Slicing is generally available on GKE, which decouples logical TPU slice formation from physical nodepool provisioning. Compared to creating a static nodepool for each TPU slice, dynamic slicing reduces AI workload startup times

Now generally available: GKE dynamic slicing for higher resilience, and efficiency for TPUs Read More »

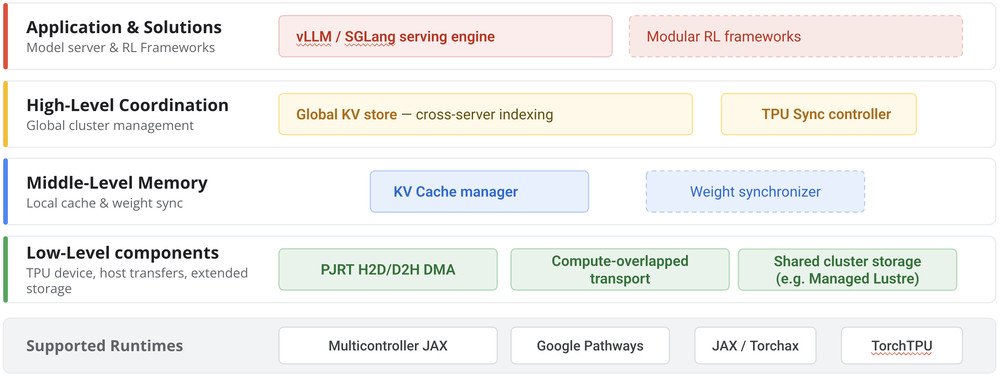
Introducing TPU Sync: Fast KV cache and weight transfer for inference and RL on TPU

As frontier AI evolves from stateless single-turn prompts to million-token agents, disaggregated serving, and continuous reinforcement learning (RL), the primary bottleneck in AI infrastructure has shifted from raw compute to orchestrating live model state — both the contextual state held in massive key-value (KV) caches during inference and the parameter state updated and broadcast from

Introducing TPU Sync: Fast KV cache and weight transfer for inference and RL on TPU Read More »

Our newest TPUs: 8tx and 8i Max, built for the agentic era

Editor’s note: This blog was originally published on News from Google. We first designed TPUs more than a decade ago motivated by Google’s internal demands, including voice recognition and language translation. Eight generations of TPUs later, the use cases have exploded, covering: i) training and serving our own Gemini models, ii) agentic workloads, iii) delivering

Our newest TPUs: 8tx and 8i Max, built for the agentic era Read More »

Cloud Pathways, a distributed ML runtime for massive accelerator fleets, now GA

Today, we are thrilled to announce the general availability (GA) of Cloud Pathways (Pathways on Cloud) on Google Kubernetes Engine (GKE) as a core runtime pillar of the Google Cloud AI Hypercomputer. Originally engineered by Google DeepMind to train and serve Google’s frontier models — including Gemini — Pathways is our distributed machine-learning runtime designed

Cloud Pathways, a distributed ML runtime for massive accelerator fleets, now GA Read More »

Introducing Z4M: storage-optimized compute for AI/ML and parallel file systems

Today, we’re excited to announce the general availability of our next-generation Storage-optimized Z4M machine series in Google Compute Engine, available as both Virtual Machine (VM) and bare-metal instances.  We built Z4M to provide storage for AI/ML training and inference workloads such as checkpointing, distributed key-value (KV) cache and parallel file systems — workloads that handle

Introducing Z4M: storage-optimized compute for AI/ML and parallel file systems Read More »

The Blueprint: Orchestrating 5,000+ AI assets for a World Cup TV spot

Welcome back to The Blueprint, a regular feature where we highlight how Google Cloud customers are tackling unique and common challenges across industries using the latest AI and cloud technologies. We hope to inspire others looking to innovate in their work. AI is rapidly transforming video production at virtually every step of the process, from

The Blueprint: Orchestrating 5,000+ AI assets for a World Cup TV spot Read More »