AI

How Amazon Finance Automation built a generative AI Q&A chat assistant using Amazon Bedrock

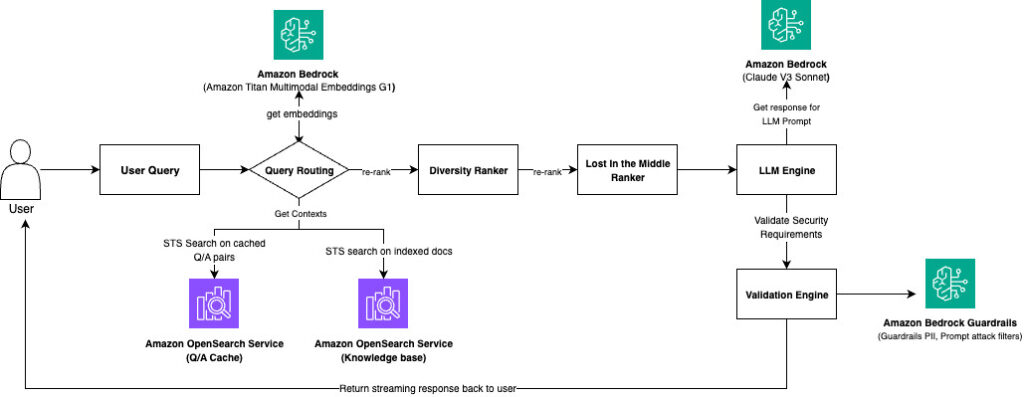
Today, the Accounts Payable (AP) and Accounts Receivable (AR) analysts in Amazon Finance operations receive queries from customers through email, cases, internal tools, or phone. When a query arises, analysts must engage in a time-consuming process of reaching out to subject matter experts (SMEs) and go through multiple policy documents containing standard operating procedures (SOPs) […]

How Amazon Finance Automation built a generative AI Q&A chat assistant using Amazon Bedrock Read More »

Photonic processor could enable ultrafast AI computations with extreme energy efficiency

The deep neural network models that power today’s most demanding machine-learning applications have grown so large and complex that they are pushing the limits of traditional electronic computing hardware. Photonic hardware, which can perform machine-learning computations with light, offers a faster and more energy-efficient alternative. However, there are some types of neural network computations that

Photonic processor could enable ultrafast AI computations with extreme energy efficiency Read More »

Cohere Rerank 3.5 is now available in Amazon Bedrock through Rerank API

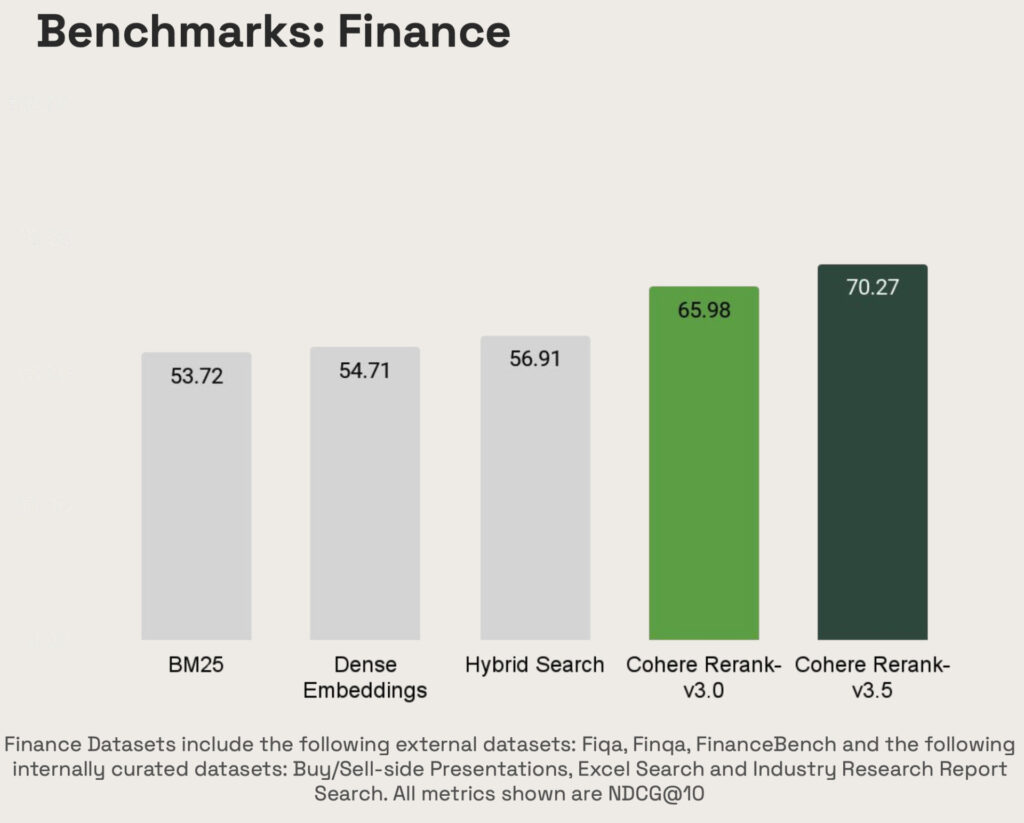
We are excited to announce the availability of Cohere’s advanced reranking model Rerank 3.5 through our new Rerank API in Amazon Bedrock. This powerful reranking model enables AWS customers to significantly improve their search relevance and content ranking capabilities. This model is also available for Amazon Bedrock Knowledge Base users. By incorporating Cohere’s Rerank 3.5

Cohere Rerank 3.5 is now available in Amazon Bedrock through Rerank API Read More »

Easily deploy and manage hundreds of LoRA adapters with SageMaker efficient multi-adapter inference

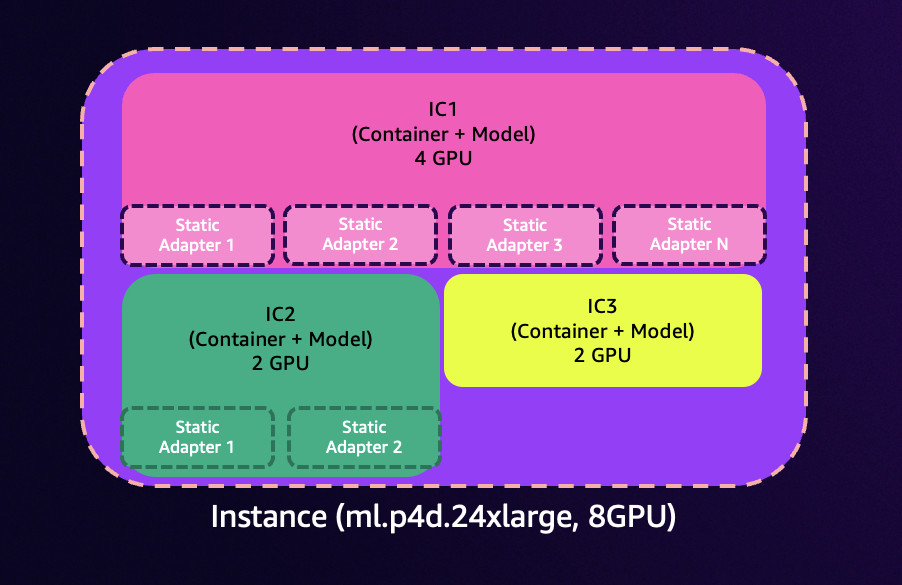
The new efficient multi-adapter inference feature of Amazon SageMaker unlocks exciting possibilities for customers using fine-tuned models. This capability integrates with SageMaker inference components to allow you to deploy and manage hundreds of fine-tuned Low-Rank Adaptation (LoRA) adapters through SageMaker APIs. Multi-adapter inference handles the registration of fine-tuned adapters with a base model and dynamically

Easily deploy and manage hundreds of LoRA adapters with SageMaker efficient multi-adapter inference Read More »

Improve the performance of your Generative AI applications with Prompt Optimization on Amazon Bedrock

Prompt engineering refers to the practice of writing instructions to get the desired responses from foundation models (FMs). You might have to spend months experimenting and iterating on your prompts, following the best practices for each model, to achieve your desired output. Furthermore, these prompts are specific to a model and task, and performance isn’t

Improve the performance of your Generative AI applications with Prompt Optimization on Amazon Bedrock Read More »

Search enterprise data assets using LLMs backed by knowledge graphs

Enterprises are facing challenges in accessing their data assets scattered across various sources because of increasing complexities in managing vast amount of data. Traditional search methods often fail to provide comprehensive and contextual results, particularly for unstructured data or complex queries. Search solutions in modern big data management must facilitate efficient and accurate search of

Search enterprise data assets using LLMs backed by knowledge graphs Read More »